
Whether you’re launching microservices in response to sudden traffic spikes, deploying new software releases, or scaling up application replicas, pod startup time is critical to maintaining a fast, responsive user experience for applications running on Google Kubernetes Engine (GKE).
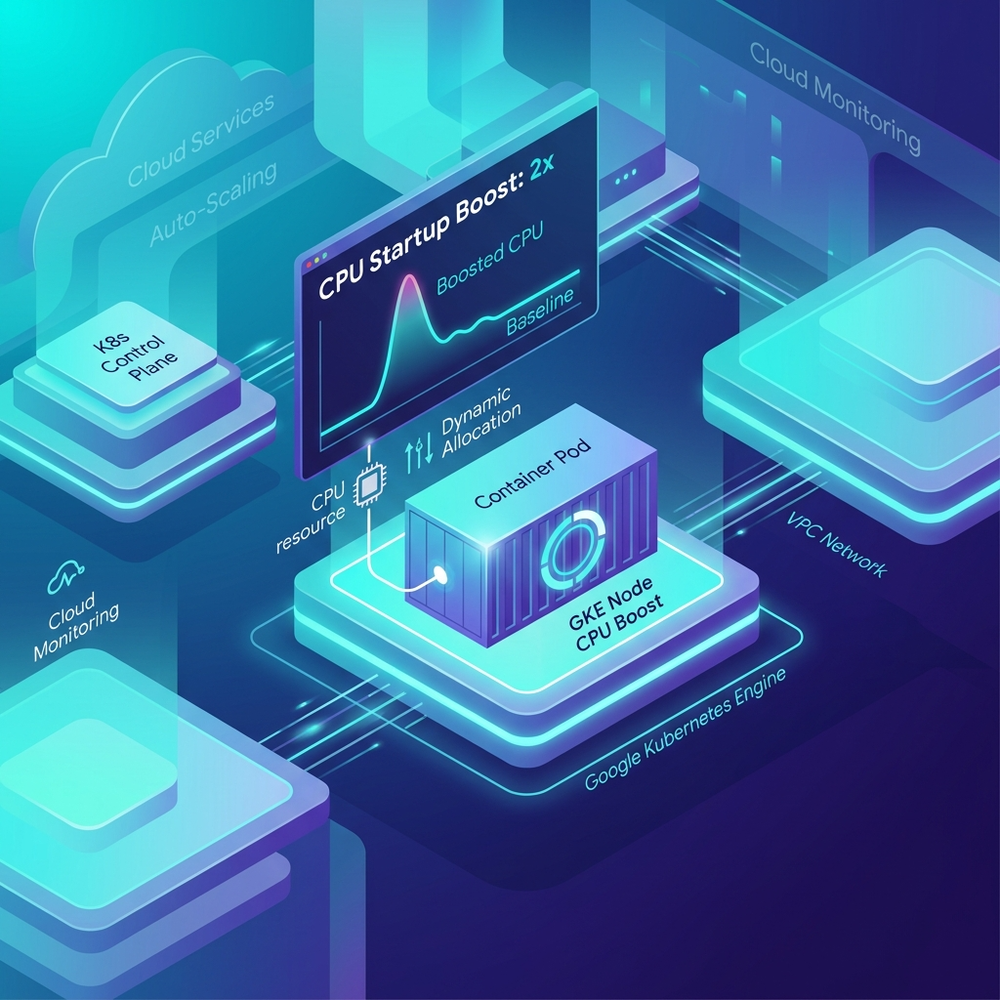
Yet, platform engineers and developers face a persistent dilemma: Applications often demand significantly more CPU power during startup than they do during steady-state operations. Sizing CPU requests for normal, steady-state usage leads to CPU throttling during launch, which can result in sluggish cold starts and readiness probe timeouts. On the flip side, over-provisioning baseline CPU requests to satisfy short-lived startup bursts wastes valuable compute resources, inflating infrastructure bills.
Today, we are excited to announce CPU startup boost for GKE in preview. Integrated directly into GKE’s Vertical Pod Autoscaler (VPA), CPU startup boost dynamically elevates a container’s CPU allocation during initialization and seamlessly scales it back to baseline steady-state levels once the application is ready – all without restarting your containers.
Why modern applications need extra CPU at boot time
When a new container launches, it may perform intensive initialization tasks before it begins serving user requests. Depending on your tech stack, the following startup workloads require substantial CPU cycles:
-
Java JVM applications: Frameworks like Spring Boot require high CPU burst capacity for class loading, classpath scanning, instantiating dependency injection containers, and running Just-in-Time (JIT) compilation.
-
Node.js servers: Apps parse JavaScript files, build complex module dependency trees (
require/import), and execute V8 engine optimization and JIT compilation passes during initial execution. -
Python and AI/ML microservices: These services spend initial cycles importing heavy libraries (such as PyTorch, NumPy, or LangChain), compiling
.pycbytecode, establishing ORM database schemas, and pre-loading cache structures.
If you size CPU requests strictly for steady-state performance, these initialization workloads experience CPU throttling on launch, delaying readiness probes. To prevent slow cold starts, teams frequently overprovision CPU requests. However, once the application stabilizes, those extra CPU resources sit idle, increasing your cloud spend without adding value.

How CPU startup boost can help
CPU Startup Boost solves this by giving your workloads temporary vCPU “boosts” during launch, and automatically returning them to baseline once initialization completes.
Key benefits:
- Faster cold starts: Reduce application initialization times by up to 2x, accelerating auto-scaling responsiveness during unexpected traffic surges.
- Optimized cloud spend: Right-size steady-state CPU requests to fit actual runtime needs rather than paying for idle startup headroom.
- Zero pod restarts: Dynamic resource resizing happens live inside the running container.
- Flexible policy controls: Apply simple pod-level multiplier factors (e.g., 2x CPU during startup) or define granular, container-specific rules for complex multi-container pods.
Under the hood: Kubernetes In-place Pod Resize
Historically, changing a pod’s resource requests or limits required deleting and recreating the pod. This disruptive process triggered container restarts, cache invalidation, and node rescheduling overhead.
To fix that, CPU startup boost builds on Kubernetes In-place Pod Resize (IPPR).
Tracked under KEP-1287, IPPR introduced dynamic, in-place resource mutation. Introduced as Alpha in Kubernetes 1.27, promoted to Beta in v1.33, and graduating to General Availability (GA) in v1.35, IPPR allows the Kubernetes control plane and kubelet to update container CPU and memory requests on running pods without restarting the container process.
GKE leverages IPPR within the VPA to apply startup CPU boosts at pod admission and smoothly step them down post-readiness.
How CPU startup boost works (pod lifecycle overview)
CPU startup boost operates across three distinct phases:
-
Admission phase: When you deploy a pod, the VPA admission webhook intercepts the creation request. It calculates the elevated CPU request based on your policy (e.g., 2x multiplier or +2 vCPUs) and injects the boosted CPU request along with tracking annotations into the pod spec.
-
Startup phase: The pod is scheduled and initialized with the boosted CPU allocation. Your application completes class loading, JIT compilation, or module parsing at top speed without experiencing CPU throttling.
-
Unboosting phase: As soon as the pod’s
readinessProbepasses (plus any configureddurationSecondscooldown delay), the VPA updater issues an in-place resize request. The CPU request steps back down to your baseline level while the container continues running uninterrupted.
Prerequisites and availability
CPU startup boost is available today in preview on GKE:
-
GKE version: Version
1.36.0-gke.4447000or later on Standard and Autopilot clusters. -
Cluster Modes: Enabled natively on GKE Autopilot (VPA is active by default). On GKE Standard, simply ensure Vertical Pod Autoscaling (VPA) is enabled.
-
Workload Support: Works with standard Kubernetes controllers, including Deployments and StatefulSets.
Getting started: Configuring CPU startup boost
Configuring CPU startup boost is as simple as adding a startupBoost section to your VerticalPodAutoscaler manifest.
Example 1: Pod-level boost with fixed steady-state (updateMode: "Off")
If you want to use VPA purely for startup boost while keeping steady-state CPU requests locked to your manifest definitions, set updateMode to "Off":
- code_block
- <ListValue: [StructValue([('code', 'apiVersion: "autoscaling.k8s.io/v1"rnkind: VerticalPodAutoscalerrnmetadata:rn name: java-app-startup-boostrn namespace: defaultrnspec:rn targetRef:rn apiVersion: "apps/v1"rn kind: Deploymentrn name: java-apprn updatePolicy:rn updateMode: "Off"rn startupBoost:rn cpu:rn type: "Factor"rn factor: 2rn durationSeconds: 10'), ('language', ''), ('caption', )])]>
In this example, GKE doubles the container’s CPU request during launch and holds the boosted allocation for 10 seconds after readiness probes pass before scaling back to baseline.
Example 2: Combining startup boost with continuous VPA auto-scaling
If you want GKE to boost CPU during launch and continuously optimize steady-state resources post-startup, set updateMode to "InPlaceOrRecreate":
- code_block
- <ListValue: [StructValue([('code', 'apiVersion: "autoscaling.k8s.io/v1"rnkind: VerticalPodAutoscalerrnmetadata:rn name: nodejs-app-vparn namespace: defaultrnspec:rn targetRef:rn apiVersion: "apps/v1"rn kind: Deploymentrn name: nodejs-servicern updatePolicy:rn updateMode: "InPlaceOrRecreate"rn startupBoost:rn cpu:rn type: "Factor"rn factor: 3rn durationSeconds: 15'), ('language', ''), ('caption', )])]>
Example 3: Granular container-level boost
For pods running sidecars (such as logging agents or service mesh proxies) that do not require extra CPU on boot, target specific app containers:
- code_block
- <ListValue: [StructValue([('code', 'apiVersion: "autoscaling.k8s.io/v1"rnkind: VerticalPodAutoscalerrnmetadata:rn name: app-container-boostrnspec:rn targetRef:rn apiVersion: "apps/v1"rn kind: Deploymentrn name: API-gatewayrn updatePolicy:rn updateMode: "Off"rn resourcePolicy:rn containerPolicies:rn – containerName: "web-app"rn mode: "Off"rn startupBoost:rn cpu:rn type: "Quantity"rn quantity: "2"rn durationSeconds: 5'), ('language', ''), ('caption', )])]>
Verifying startup boost in your cluster
You can verify that GKE applied and downscaled the startup boost using kubectl:
1. Inspect pod annotations: Check for the vpaCpuStartupBoost tracking annotation:
- code_block
- <ListValue: [StructValue([('code', 'kubectl get pod -o yaml’), (‘language’, ”), (‘caption’, )])]>
Look for annotations indicating the original baseline and boosted CPU requests.
2. Monitor in-place resize events: Confirm that GKE downscaled the CPU request back to baseline after readiness:
- code_block
- <ListValue: [StructValue([('code', 'kubectl get events –field-selector reason=InPlaceResizedByVPA'), ('language', ''), ('caption', )])]>
An event with reason=InPlaceResizedByVPA confirms successful in-place downscaling post-startup.
Best practices for production workloads
-
Pairing with Horizontal Pod Autoscaler (HPA): When using HPA alongside CPU startup boost, ensure a robust
readinessProbeis defined and keepdurationSecondsshort (e.g.,0s–10s). This prevents HPA from falsely interpreting initialization CPU spikes as high steady-state load. -
Handle traffic spikes with GKE capacity buffers API: By reducing the startup tax at scale, you can achieve higher workload density on fewer nodes to improve overall utilization. Consider adopting the GKE capacity buffers API to absorb sudden traffic surges with minimal operational overhead while maintaining strict SLOs.
-
GKE Autopilot resource ratios: On GKE Autopilot, remember that pods must maintain valid CPU-to-memory ratios. Ensure baseline memory allocations accommodate the boosted CPU ratio during startup.
Get started today
CPU startup boost gives GKE users the best of both worlds: lightning-fast cold starts for CPU-intensive workloads like Java, Node.js, and Python, paired with maximum resource efficiency and lower cloud costs.
Ready to accelerate your GKE workloads?
-
Explore the GKE CPU startup boost documentation.
-
Learn more about Vertical Pod Autoscaling on GKE.
-
Try CPU startup boost on your GKE Standard or Autopilot clusters running GKE
1.36.0-gke.4447000or later!