
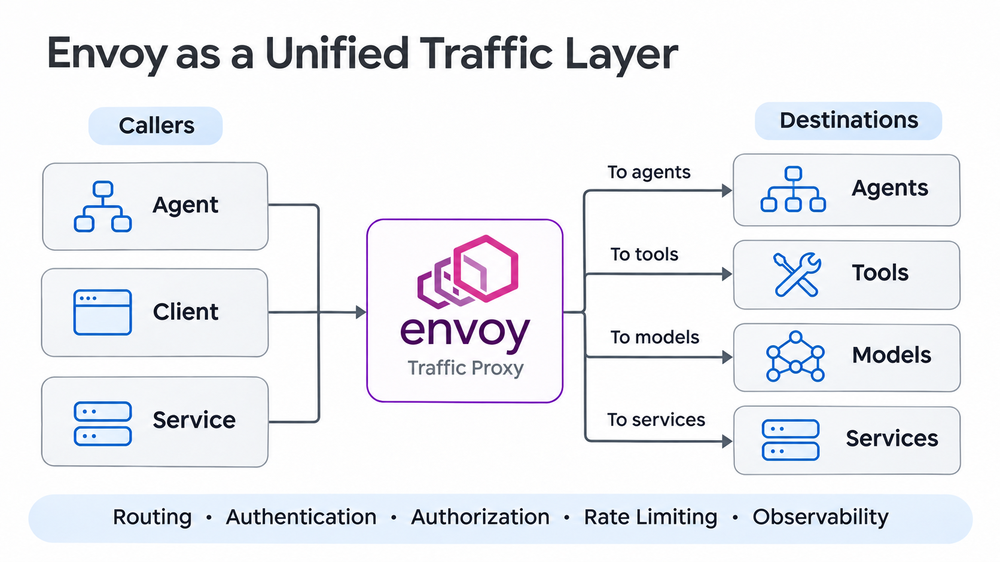
At Google Cloud, we believe the next generation of AI and agentic systems must be built on open, battle-tested foundations. Envoy, an open-source edge and service proxy designed for cloud-native applications, has already transformed microservices and modern cloud networking, powering everything from Google Cloud’s Application Load Balancers to the Agent Substrate dataplane on Google Kubernetes Engine. Now, Envoy is uniquely positioned to become the open standard for AI traffic, MCP tooling, and agent-to-agent communication.
Earlier this year, we presented the technical case for Envoy networking in the agentic AI era, examining how autonomous AI agents fundamentally challenge traditional Layer 7 networking assumptions. Unlike microservices, autonomous agent workloads choose who they communicate with. In addition, their routing attributes live deep within request bodies, with their traffic governed by token budgets as well as request rates, and their multi-turn reasoning loops requiring stateful session affinity and strict tool execution boundaries.
At Google Cloud, we have been working hard to develop Envoy for the agentic era. Read on for a closer look at how Envoy has evolved to better support autonomous agents, giving developers the performance and portability of an open-source ecosystem, backed by enterprise security and scalability.
Why autonomous agents challenge traditional L7 proxies
Over the past decade, Envoy became the industry standard for cloud-native traffic management by operating cleanly at Layer 4 (TCP/UDP connection management) and Layer 7 (URI, method, and header-based routing).
Autonomous agents introduce two higher-order protocol layers:
-
Layer 8 (agentic interaction protocols): such as LLM APIs, Anthropic’s Model Context Protocol (MCP) and Google’s Agent2Agent (A2A), running over JSON-RPC 2.0 or gRPC. Critical policy attributes—such as
tools/call,tool_name: "execute_sql", ormodel: "gemini-1.5-pro"—are serialized inside the request payload. -
Layer 9 (agent framework interfaces): Coordination frameworks such as UCP, AP2, and Google Cloud’s Agent Development Kit, where multi-turn workflows produce dynamic token consumption and non-linear execution graphs.
Fronting these workloads with traditional L7 proxies creates four major architectural challenges:
-
Payload blindness: Nearly all LLM traffic shares the same paths (such as
/v1/chat/completions), so a header-based proxy cannot distinguish between a low-cost query and an expensive 500,000-token prompt, or one model from another. -
Request rate limiting fallacy: One request per minute with a massive context window can use more accelerator compute and memory bandwidth than dozens of short queries, and agent loops can burn through budgets unnoticed.
-
Stateless load balancing: Each turn of an agent’s conversation should go back to the server that already remembers it. Traditional load balancers send it to whichever server is next, so the model has to start over for every turn, this wastes time and GPUs.
-
Ungoverned tool execution: Agents query databases, execute code in sandboxes, and call third-party APIs. Without inline inspection of MCP tool calls, organizations risk prompt injection, data exfiltration, and runaway billing loops.
The core pillars of Envoy’s agentic stack
To address these challenges, Envoy provides capabilities that turn the network into an active governance layer:
|
Core Pillar |
Operational Functionality |
|---|---|
|
1. Native body parser |
Payload blindness: Read request bodies, not just headers.Line-rate payload normalization across OpenAI, Anthropic, and Gemini schemas with SSE stream handling. |
|
2. Tokenomics engine |
Request-rate fallacy: Count tokens, not just requests.Pre-inference token estimation, tokens per minute (TPM)/tokens per day (TPD) rate limiting |
|
3. Model & MCP routing |
Stateless load balancing: Keep agent sessions on the right serversEndpoint Picker (EPP) model dispatch, KV-cache prefix affinity, MCP Stateless support. |
|
4. AI security guardrails |
Ungoverned tool execution: Policy tool calls.Inline policy, decision point (ext_proc) callouts for guardrails: Model Armor, ShieldGemma, and data loss prevention. |
1. Native wire-format body parsing and transcoding
Client applications often get locked into specific model APIs. For example, client code built for OpenAI’s schema cannot communicate with Anthropic’s endpoints or Google’s Gemini without client-side translation layers.
To help, Envoy ecosystem includes native body parsers that normalize requests across diverse model families, providing:
-
Client abstraction: Upstream applications send a standardized schema. Envoy inspects the JSON payload at line-rate, extracts the target model, and dynamically transcodes the request into the downstream provider’s native format.
-
No application code changes: Switching from an external commercial model to a self-hosted open-source model (such as Gemma or Llama on vLLM) requires only an Envoy configuration update. Application code remains unchanged.
-
Streaming token extraction: Envoy parses server-sent events (SSE) response streams in real time, capturing token counts from usage chunks while maintaining ultra-low time-to-first-token latency.
2. Tokenomics engine: token-aware traffic management
In AI networking, tokens are the fundamental unit of capacity. Envoy replaces coarse request counters with token-aware traffic management features such as:
-
Token rate limiting: Enforces tokens per minute (TPM) and tokens per day (TPD) limits per tenant, project, or model.
-
Pre-inference throttling: Envoy estimates input tokens from request payload bytes and extracts actual token usage from LLM responses to record in a quota database, rejecting subsequent over-quota requests with an HTTP
429before they reach the inference cluster. -
Runaway loop protection: Autonomous agents can enter recursive reasoning loops. By tracking cumulative token consumption and message counts per session or agent ID, Envoy throttles multi-turn sessions once an agent exceeds its assigned budget.
3. Model routing and Model Context Protocol (MCP) support
Envoy manages traffic for both downstream model backends and outbound tool calls, with:
-
KV-cache prefix affinity: Using the Kubernetes Gateway API Inference Extensions and Endpoint Picker (EPP), Envoy routes prompts sharing identical system instructions to the GPU worker currently holding that cache in memory, reducing latency.
-
Model retry and fallback: If a primary model returns a 429 status code or fails, Envoy automatically retries or redirects the request to a secondary model pool with zero client interruption.
-
MCP tool routing: For MCP agents, Envoy routes requests via JSON-RPC 2.0 bodies and HTTP headers. Per the 2026-07-28 MCP specification, Envoy uses
Mcp-MethodandMcp-Nameheaders for zero-body-parsing routing to backend servers. Backends reject header-body mismatches with an HTTP400/-32020(HeaderMismatch) error to prevent tampering.
4. AI security guardrails
Inline safety filtering cannot come at the expense of network throughput. To prevent this, Envoy provides security callouts: Using standardized external processing (ext_proc), Envoy connects to dedicated policy decision engines — such as Google Cloud’s Model Armor, ShieldGemma, or local classifiers — to detect prompt injections and sensitive data leaks with minimal latency overhead.
High-density infrastructure: Envoy and Agent Substrate
In enterprise production environments, agents frequently spend time idle between user queries or long-running tool executions. Running hundreds of thousands of idle agents in dedicated containers or virtual machines can create prohibitive infrastructure costs.
Envoy pairs directly with high-density execution runtimes like Agent Substrate to provide:
-
Scale-to-zero traffic steering: Agent Substrate uses lightweight isolation runtimes (such as Cloud Hypervisor, microVMs and gVisor application sandboxes) that can suspend and resume in milliseconds. When traffic arrives for a suspended agent, Envoy buffers the initial packet while signaling the runtime to resume the instance, completing the end-to-end resume in milliseconds.
-
Egress perimeter defense: Envoy functions as both an ingress and egress gateway for agent environments, routing the inbound traffic and restricting outbound network calls to verified domains and preventing untrusted autonomous code from reaching unauthorized endpoints.
Getting started
Envoy has evolved into an intelligent, extensible networking layer designed specifically for the unique demands of multi-agent architectures. To begin building with the agentic stack in Envoy:
-
Explore the code: Review the Envoy proxy and Agent Router implementations on Github and examine the open-source sample configurations.
-
Join the community: Participate in CNCF, Gateway API, and Kubernetes AI Gateway Working Group to collaborate on standardized inference APIs, MCP routing specifications, and token management conventions.