
Editor’s note: This blog was originally published on News from Google.
We first designed TPUs more than a decade ago motivated by Google’s internal demands, including voice recognition and language translation. Eight generations of TPUs later, the use cases have exploded, covering: i) training and serving our own Gemini models, ii) agentic workloads, iii) delivering services to Google Cloud customers on our cloud infrastructure, and most recently, iv) allowing customers to deploy TPUs directly into their own data centers. TPUs are now a rapidly growing business with nearly 100 customers — including frontier labs, trading firms, retailers, universities, and more.
At Google Cloud Next in April, we introduced two new specialized TPUs in the same generation — 8t for large-scale training and 8i for real-time reasoning. TPU 8t and 8i offer up to 2.7 times better training performance and 80% better inference price performance, respectively, versus our previous generation of TPUs.
Today, we’re taking that a step further, expanding our eighth-generation TPU portfolio with two additional systems: TPU 8i Max for massive context windows and the highest compute density per rack, and TPU 8tx for secure and confidential inference. This is the first time we have introduced four TPU systems in a single year.
Our expanded eighth-generation TPU portfolio: TPU 8t, TPU 8i, TPU 8tx, and TPU 8i Max.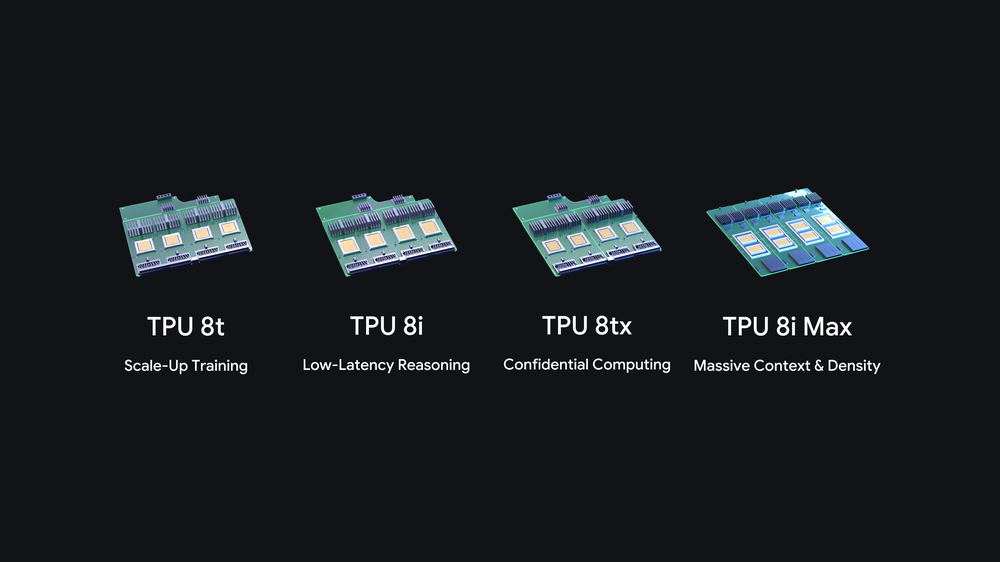
While we’ve always co-designed our TPUs in partnership with Google DeepMind, we’re now increasingly getting feedback from external organizations on their specific needs. With computing moving from human to agent scale, businesses are asking for accelerators that can reason across AI models’ massive context windows. In addition, some highly regulated customers are asking for specialized encryption capabilities for unique workloads.
The new TPU systems we are announcing today address this new reality. Coupled with our recent PyTorch announcements, our aim is to make TPUs more easily accessible to every developer and Cloud customer. By combining modular custom silicon with an open and easy-to-use software stack, we can deliver new hardware and system configurations at the pace of the AI industry.
Building the computer around the chip
Today, we’re announcing two new TPU systems — and there’s an important difference between a new chip and a new system.
Designing a new chip means laying out billions of microscopic transistors on a silicon wafer in a multi-year process bound by the laws of physics and a complex, long-duration manufacturing lifecycle. A system, on the other hand, is about how we bring together the compute, networking, and storage around the chip. This can include how they are packaged with the chips, to quickly meet emerging customer needs and research use cases.
When we built our very first TPU more than a decade ago, we knew AI software would evolve much faster than silicon manufacturing ever could. So we made a foundational bet on system balance and modularity, architecting our TPUs as building blocks as part of our AI Hypercomputer, so engineers could rapidly adjust packaging, high-speed memory, optical networking, and security around them. That approach allows us to deliver specialized supercomputers in a matter of months rather than years.
Specializing for secure, high-context AI
Each system in our eighth-generation TPU portfolio targets a distinct part of the AI lifecycle. TPU 8t and TPU 8i established the baseline for this generation of chips:
-
TPU 8t was designed to be a training powerhouse for massive foundation models with maximum “goodput” — or the useful intelligence delivered per watt of energy used.
-
TPU 8i is the reasoning engine, designed to break the memory wall, cutting inter-chip communication delays by up to half.
Now, as enterprises bring autonomous agents into production, we have created two new configurations of these foundational systems to solve two urgent new challenges: hardware-level data security and million-token context scale.
TPU 8tx
TPU 8tx, our third eighth-generation system, is optimized for secure and confidential inference and is also great for small-scale training. It’s built for regulated enterprises and governments running frontier or proprietary models and autonomous agents alongside their most sensitive data.
Normally, data is encrypted when stored or sent over a network, but has to be unlocked in memory while a computer processes it. Built on the same silicon as TPU 8t and paired with custom AMD CPU hosts, TPU 8tx builds security directly into the hardware layer, keeping sensitive data and model weights protected and isolated even while in active use. And by adopting the same low-latency Boardfly network we created for real-time reasoning, TPU 8tx keeps multi-step agents moving, delivering up to 2x lower latency compared to TPU 8t with a near-zero performance penalty.
Pairing training-grade compute with a fast inference network also means organizations can simultaneously run and customize their models on a single system. TPU 8tx enables teams to fine-tune models using their private data, distill large models into smaller ones, and train their agents through reinforcement learning, all without needing to migrate sensitive data between separate clusters.
Designed for sensitive enterprise workloads, TPU 8tx provides hardware-level confidential compute for private fine-tuning and secure agent execution.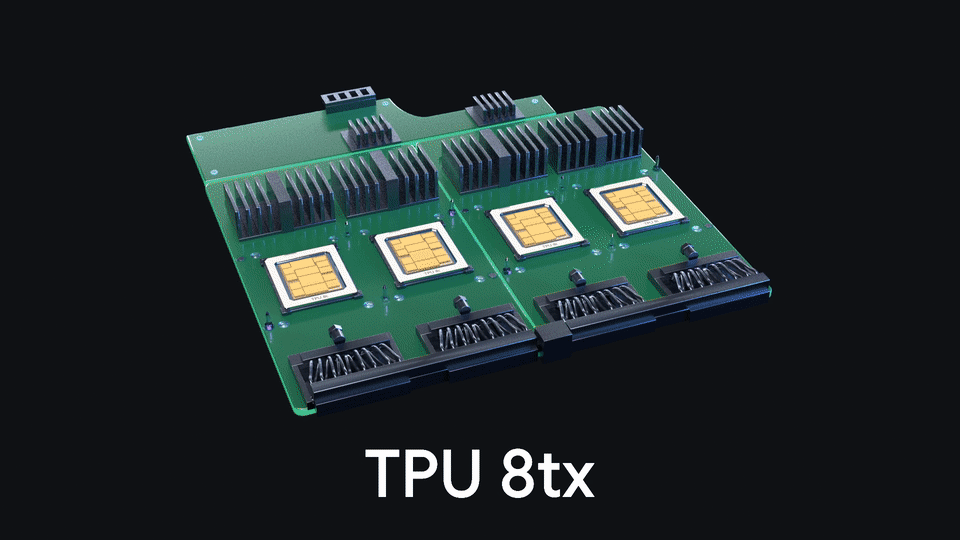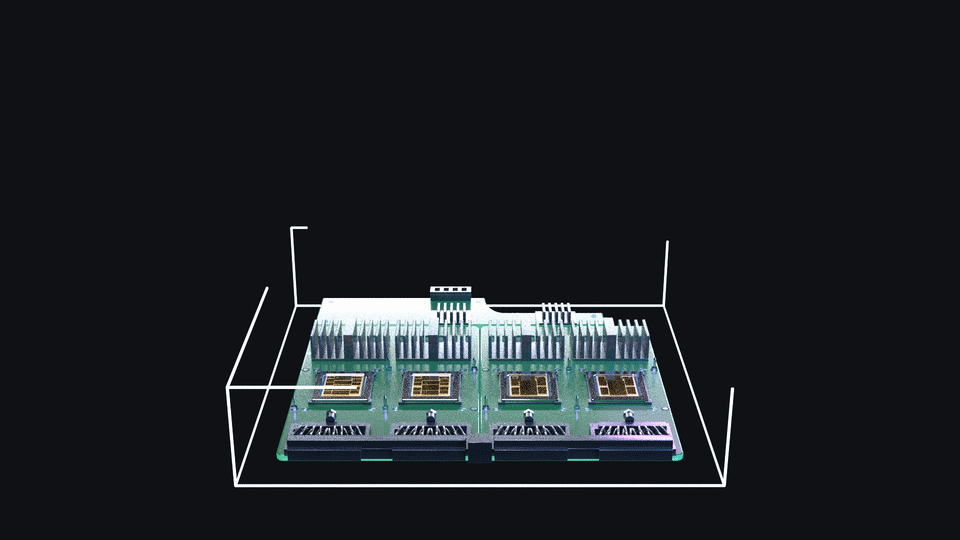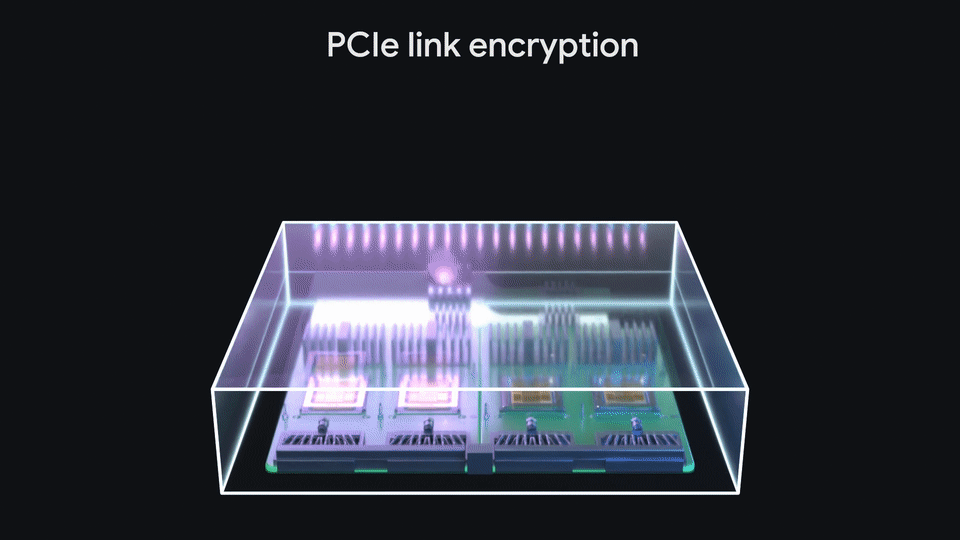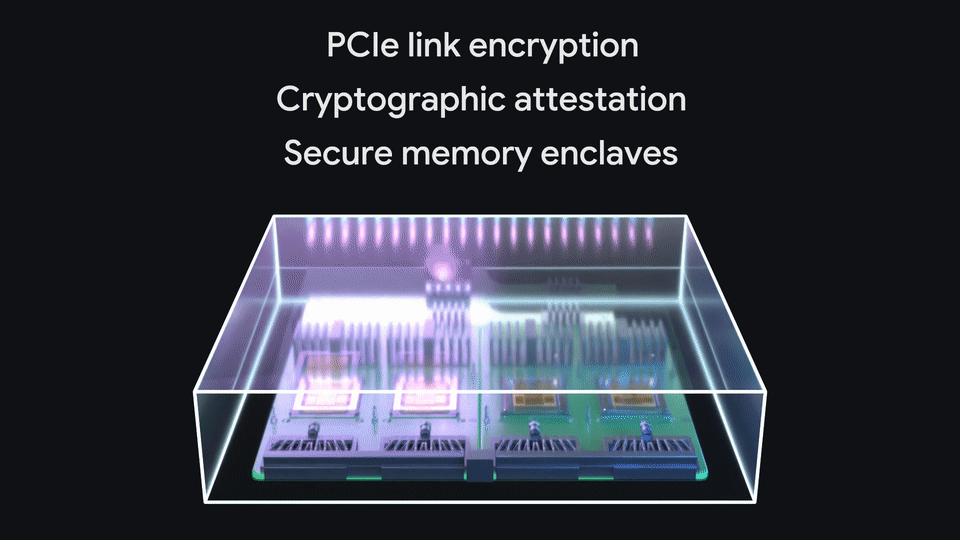
TPU 8i Max
Our fourth system, TPU 8i Max, is built for a different problem: the memory wall.
When dozens of AI agents work together across an entire software codebase or hours of video at once, memory bandwidth quickly becomes the bottleneck. So we took two low-latency TPU 8i chips and combined them onto a single package.
TPU 8i Max scales compute and memory in lockstep, delivering double the compute, double the SRAM and double the HBM bandwidth of TPU 8i, so processors remain equipped with essential data and so that large workloads do not stall. Further, because TPU 8i Max fits twice the silicon within the existing rack footprint, data centers can deploy significantly more computing power per square foot and per watt.
The dual-chip TPU 8i Max system, engineered for massive context windows and maximum compute density.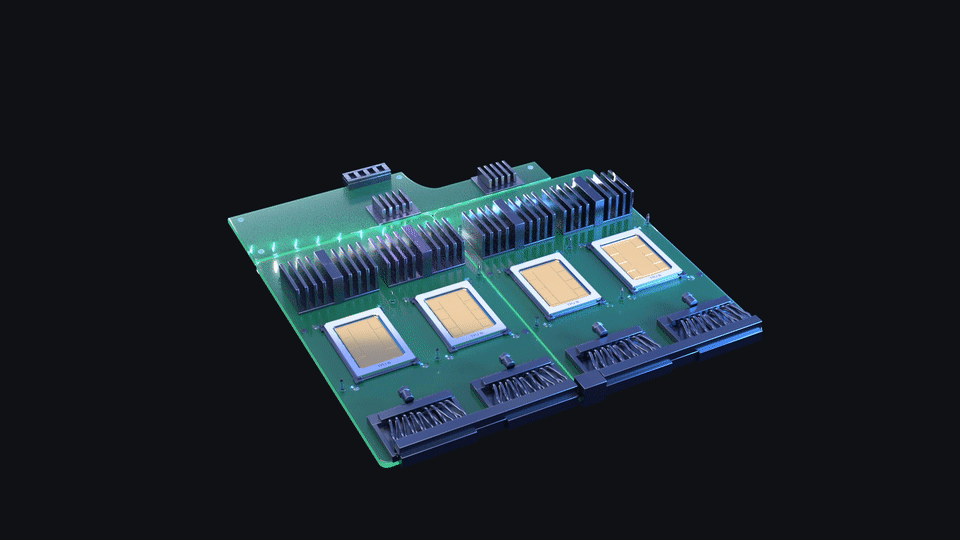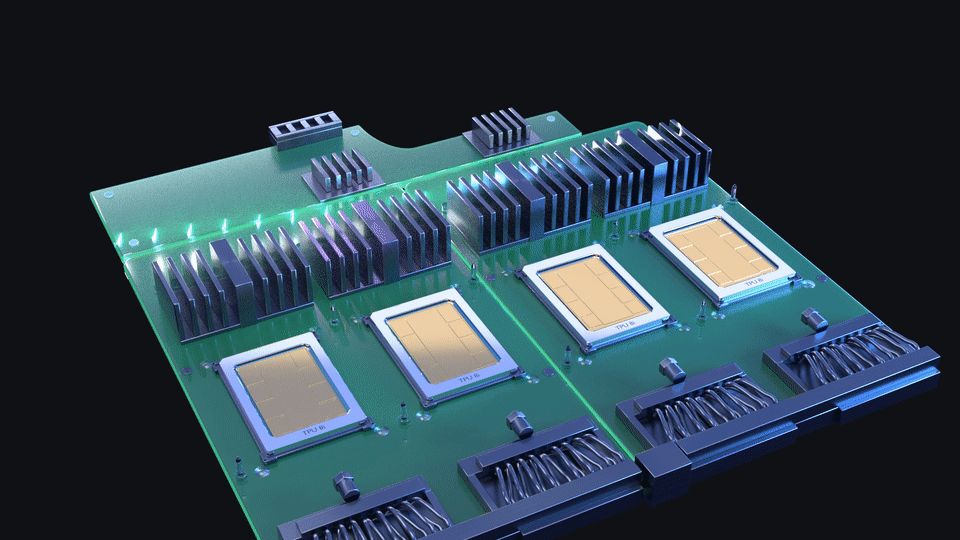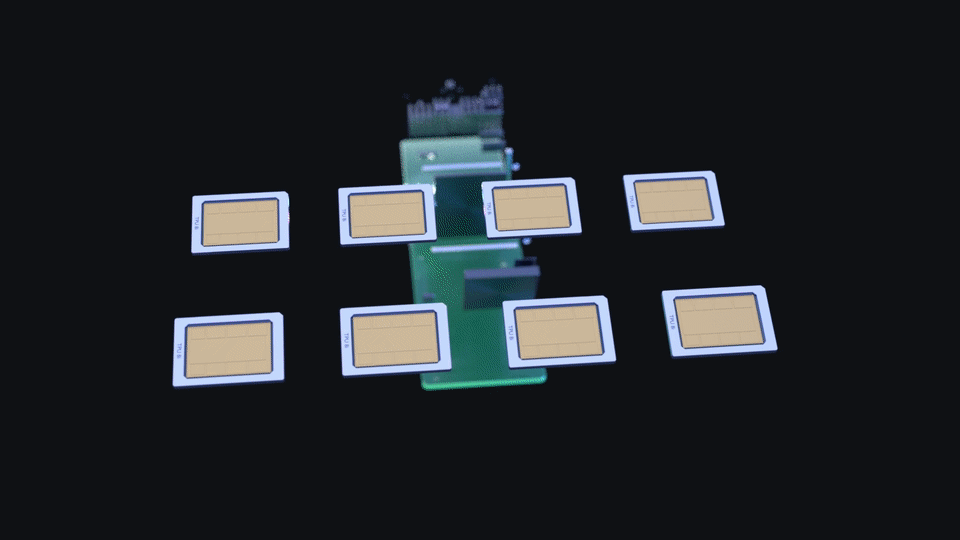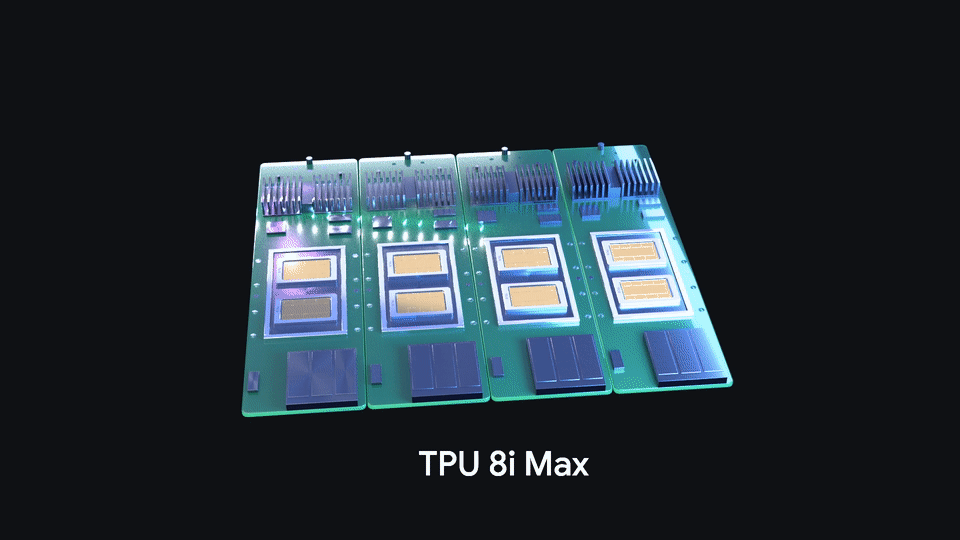
While flexible across workloads, together the four systems in our eighth-generation TPUs give customers a purpose-built accelerator for every stage of the agentic lifecycle. TPU 8t for scale-up training, TPU 8i for low-latency reasoning, TPU 8tx for confidential computing, and TPU 8i Max for massive context windows and the highest compute density per rack.
Opening up TPUs to every developer
When we launched the first TPU more than a decade ago, there were only a handful of companies running workloads that needed the processing power of a TPU. The use cases were specialized, so engineers would use optimized frameworks and hand-tuned code.
Over the years, as AI has advanced, more and more companies began using accelerators. Now, AI adoption is at a point where TPUs are excellent for a wide range of companies and use cases, and as a result, we’ve been working systematically to remove barriers to adoption so that TPUs are as easy-to-use as general-purpose hardware.
This investment comes together today across these key areas:
-
Opening up TPU development to every PyTorch developer; no code rewrites needed: Last month, we open-sourced TorchTPU, so PyTorch code and Hugging Face models now run natively on TPUs, alongside out-of-the-box TPU backends for leading open-source inference engines like vLLM and SGLang. And to make hardware optimization effortless, our new open-source TPU agent suite (now in preview) plugs directly into coding tools like Claude Code, Cursor, and Google Antigravity to automate TPU onboarding in minutes, diagnose bottlenecks, and autotune custom kernels using plain language. For production deployments, our new open-source XLA Serving Engine lets you train models in Python and serve them directly in a low-latency C++ runtime across TPUs, GPUs, and CPUs.
-
Industry-leading production performance on InferenceX and AgentX benchmarks: In production, what really matters is outcomes on real AI workloads rather than theoretical peak chip speeds. On industry-standard InferenceX and AgentX benchmarks, which test realistic agentic coding and long-context work, our native vLLM-TorchTPU software stack on TPUs achieved state-of-the-art price-performance marks. New evaluations demonstrate these advantages extend across a wide range of frontier open models and open-source serving stacks while maintaining high model accuracy. Upcoming software optimizations on this same hardware will drive those results even further.
-
Eliminating idle compute waste for autonomous agents: Because AI agents are stateful, they frequently pause for seconds or hours while waiting on a database lookup, an external software tool, or human feedback. To make our accelerators more power-efficient during those pauses, our new Agent Compute Engine software automatically suspends idle agent sessions and shifts working memory off the chip in milliseconds, cutting operational infrastructure costs.
-
Breaking through the memory wall with the model-state layer (TPU Sync): Building the computer around the chip also means unifying memory, storage, and networking in software. As agents reason across million-token contexts and continuous reinforcement learning (RL) loops, memory quickly becomes the bottleneck. We’re open-sourcing TPU Sync, the model-state layer for TPU clusters. TPU Sync turns chip HBM, host DRAM, shared storage, and the data center network into a single, co-designed memory hierarchy — automatically tiering massive KV caches off the chip in milliseconds, streaming context across disaggregated prefill and decode nodes, and synchronizing RL weights to cut KV transfer latency and Time to First Token (TTFT) by more than 90%.
-
Scaling distributed workloads across TPUs from a single controller: Now generally available on Google Kubernetes Engine (GKE), Cloud Pathways brings the Google DeepMind runtime behind Gemini to every Google Cloud customer. Using a single-controller architecture and pathwaysutils, you can orchestrate large-scale TPU systems across multiple slices as if they were one local machine for pre-training, reinforcement learning, and multihost inference. Cloud Pathways keeps long-running jobs moving through hardware disruptions with colocated Python sidecars, sub-minute slice hot-swapping, and elastic resharding.
-
Stitching custom TPU topologies on-demand with GKE dynamic slicing: Now generally available, GKE dynamic slicing decouples physical hardware provisioning from logical slice formation using optical circuit switching (OCS) technology. By dynamically assembling TPU cubes into larger topologies (super-slicing) or partitioning them into smaller, isolated workloads (sub-slicing) on-the-fly, this update completely eliminates rigid, manual nodepool recreation cycles. This topology agility slashes job startup times by up to 5x and accelerates fault recovery by up to 4.5x, maximizing overall fleet utilization and workload goodput across all TPUs.
Co-designing with a decade of experience
Shipping four TPU systems and a unified, open software stack in a single year only happens when silicon architects, networking engineers, compiler teams, and Google DeepMind researchers build side-by-side.
Increasingly, we’re even tapping into AI to ideate and build the next generation of AI infrastructure. From using Google DeepMind’s AlphaChip reinforcement learning system to using Gemini to deliver chip layouts in hours rather than weeks, we’re using TPU-powered AI services to rapidly accelerate next-generation TPU hardware development. This is true co-design and a unique Google differentiator.
Learn more about our new TPU systems by tuning into today’s broadcast at 9 a.m. PT.